qbcompiler.configs.models.HessianQuantConfig Class Reference#
|
Mobilint SDK qb Compiler v1.3
MCS002-EN
|
qbcompiler.configs.models.HessianQuantConfig Class Reference
Configuration for HessianQuant algorithm. More...
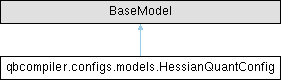
Inheritance diagram for qbcompiler.configs.models.HessianQuantConfig:
Classes | |
| class | Attributes |
Public Member Functions | |
| "HessianQuantConfig" | with_updates (self, **kwargs) |
| Return a copy with updated fields. | |
Static Public Attributes | |
| model_config | |
| bool | apply = Field(default=False, description="If true, apply HessianQuant") |
| str | hessian_dtype |
| str | accumulation_device |
| Attributes | |
| default_factory | |
| alias | |
Detailed Description
Configuration for HessianQuant algorithm.
Defines parameters controlling whether and how HessianQuant is applied during quantization, including layer-level inclusion/exclusion lists.
- Parameters
-
apply bool. If true, apply HessianQuant hessian_dtype str. Storage dtype for the accumulated HessianQuant Hessian. bf16 halves its memory footprint (host RAM when the Hessian lives on CPU, VRAM when on GPU) — critical for large models such as MoE with thousands of expert FFN Hessians. Compute stays float32 regardless: the per-batch matmul and accumulation run in float32 and the solve upcasts back to float32; only the persistent accumulator is bfloat16.:
0: fp32 - Store the Hessian in float32.
1: bf16 - Store the Hessian in bfloat16 (half the memory).
accumulation_device str. Device the HessianQuant Hessian is accumulated on during calibration. gpu accumulates on the calibration device, which is 3-5x faster because the whole d x d accumulator is otherwise copied off the device once per layer per batch; the Hessian is parked on the host as soon as the last batch is in, so this does not raise peak VRAM for the rest of the compile. cpu accumulates on the host instead, bounding VRAM during calibration itself for models whose summed Hessian does not fit alongside the activations. auto follows resourceManagement.useGPUOnlyForCalibration, which is the knob that already says whether this compile is VRAM-bound: false picks gpu, true picks cpu. Resolved once at config load and logged; a CPU compile always accumulates on the host regardless.:
0: auto - Follow useGPUOnlyForCalibration: false picks gpu, true picks cpu.
1: cpu - Accumulate on the host, bounding VRAM during calibration itself.
2: gpu - Accumulate on the calibration device, then park on the host.
attributes Attributes. HessianQuant algorithm attributes
Member Function Documentation
◆ with_updates()
| "HessianQuantConfig" qbcompiler.configs.models.HessianQuantConfig.with_updates | ( | self, | |
| ** | kwargs ) |
Member Data Documentation
◆ model_config
|
static |
◆ apply
|
static |
◆ hessian_dtype
|
static |
Initial value:
= Field(
default="fp32",
alias="hessianDtype",
description="Storage dtype for the accumulated HessianQuant Hessian. bf16 halves its memory footprint (host RAM when the Hessian lives on CPU, VRAM when on GPU) — critical for large models such as MoE with thousands of expert FFN Hessians. Compute stays float32 regardless: the per-batch matmul and accumulation run in float32 and the solve upcasts back to float32; only the persistent accumulator is bfloat16.",
)
◆ accumulation_device
|
static |
Initial value:
= Field(
default="auto",
alias="accumulationDevice",
description="Device the HessianQuant Hessian is accumulated on during calibration. gpu accumulates on the calibration device, which is 3-5x faster because the whole d x d accumulator is otherwise copied off the device once per layer per batch; the Hessian is parked on the host as soon as the last batch is in, so this does not raise peak VRAM for the rest of the compile. cpu accumulates on the host instead, bounding VRAM during calibration itself for models whose summed Hessian does not fit alongside the activations. auto follows resourceManagement.useGPUOnlyForCalibration, which is the knob that already says whether this compile is VRAM-bound: false picks gpu, true picks cpu. Resolved once at config load and logged; a CPU compile always accumulates on the host regardless.",
)
◆ Attributes
|
static |
◆ default_factory
|
static |
◆ alias
The documentation for this class was generated from the following file:
Generated by
 1.14.0